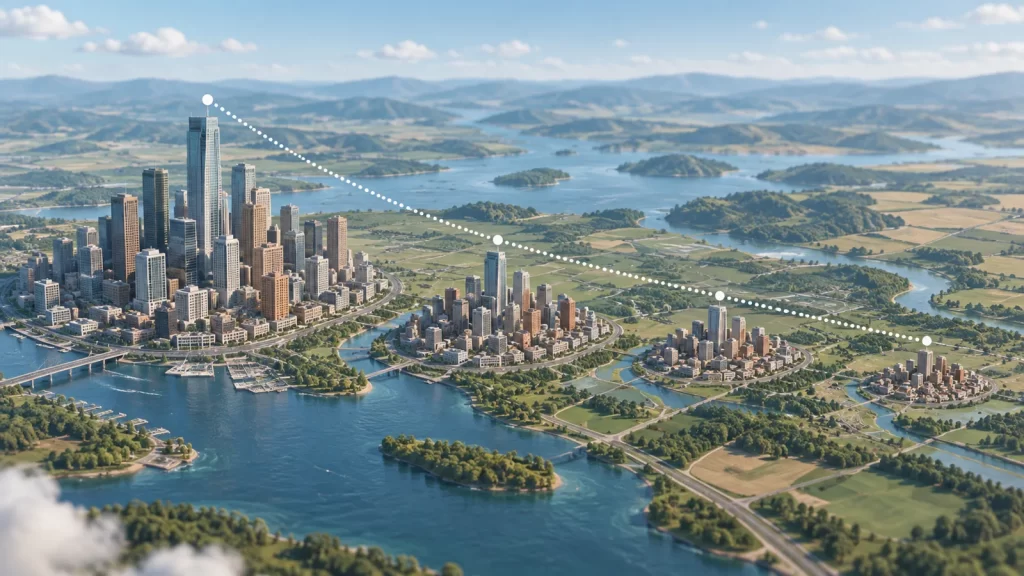
Quick answer: The rank-size rule is a benchmark for comparing the populations of cities after they are ordered from largest to smallest. In its simplest form, the city in position two is expected to have about half the population of the largest city, the city in position three about one third, and the city in position four about one quarter. This is an approximate pattern, not a rule that every country must obey. Its usefulness depends on how a city is defined, which places are included, and when their populations were measured.
What the rank-size rule means
Begin with a list of comparable settlements. Sort their populations from largest to smallest and give the largest rank 1, the next largest rank 2, and so on. The simple rank-size formula says that the population at rank r is approximately the largest population divided by r. If the largest metropolitan area contains 12 million residents, the benchmark for rank 2 is 6 million, for rank 3 is 4 million, and for rank 4 is 3 million. These values are reference points. Real cities rarely land on them exactly.
The rule is often discussed as a special case of Zipf’s law for cities. It describes a possible relationship between rank and size across a system of places. It does not say that a country’s second city should be forced to half the size of its first, and it does not say that a city will grow to its benchmark next year. The word ‘rule’ can make the idea sound more certain than the evidence warrants. A useful explanation therefore pairs the formula with an explicit warning: compare actual data with the benchmark and explain any departure without treating the formula as a law of nature.
Urban geographers use the pattern because it makes a question measurable. Instead of saying that a capital ‘looks too large,’ a researcher can ask how large it is compared with other places of the same kind, in the same year, under the same boundaries. A ratio, a table, or a graph can reveal whether one center dominates or whether several large centers share activity. It does not identify the cause of that pattern by itself. To understand causes, one must examine migration, employment, transport, policy, history, and geography separately.
Formula and a worked example
Write the simple relationship as P(r) = P(1) / r. Here P(1) is the population of the largest city or urban area, r is a positive whole-number rank, and P(r) is the benchmark population for that rank. The formula starts at rank 1; rank zero has no meaning in this exercise. In practice the equality sign is an idealization. If the first area has 12 million people, rank 5 has a benchmark of 12 million divided by 5, or 2.4 million. Rank 6 has a benchmark of 2 million. A city with an observed population of 2.2 million at rank 5 is near, but below, that simple expectation.
Suppose the five largest areas in an imaginary country have populations of 12.0, 5.4, 3.8, 3.5, and 2.2 million. The simple benchmark sequence is 12.0, 6.0, 4.0, 3.0, and 2.4 million. At rank 2, the observed value is 0.6 million below the benchmark; at rank 4 it is 0.5 million above it. This does not make either city ‘wrong.’ The comparison highlights where the actual hierarchy bends away from a mathematical reference. Because the data are fictional, they illustrate arithmetic without pretending to describe a real country’s present population.
A useful second column is the ratio of observed size to benchmark size. At rank 2 in this example, 5.4 divided by 6.0 equals 0.90. At rank 4, 3.5 divided by 3.0 is about 1.17. A ratio of one matches the benchmark; a smaller ratio means the observed area is smaller, and a larger ratio means it is larger. The measure is easy to explain, but it should not be interpreted without context. If population estimates are rounded or city boundaries are disputed, a small numerical gap may be less important than it appears.
To check your work, multiply the ideal population at each rank by its rank. Each result should equal the largest population: 6 million times 2, 4 million times 3, and 3 million times 4 all give 12 million. This check helps catch a common error in which a student divides the preceding city’s population rather than the largest city’s population. The formula uses the same top population each time. When a question gives an observed rank and asks for a benchmark, identify the largest area first, keep units consistent, and state the answer as an approximation.
Why the graph can be misleading
On ordinary axes, a plot of population against rank under the simple formula bends downward. The drop from rank 1 to rank 2 is large, while later steps become smaller. A straight line is not what the exact inverse relationship produces on a standard linear-axis chart. A frequent teaching mistake is to draw such a plot, expect a straight line, and then describe any curve as a failure of the rule. The curve is exactly what the formula predicts on those axes. Before judging a chart, read both axis scales.
Researchers often use logarithmic scales for both rank and population. Taking logarithms of P(r) = P(1) / r gives log P(r) = log P(1) – log r. If log rank is horizontal and log population vertical, the exact simple rule is a straight line with slope negative one. The direction of the axes matters: papers that put log rank on the vertical axis report a differently oriented slope. Logarithms do not change the underlying populations; they change the visual scale so multiplicative relationships are easier to inspect.
For a classroom exercise, plot the 12-million benchmark sequence first with ordinary axes, then switch both axes to logarithmic scales. You should see a curve in the first graph and aligned points in the second. Add the five fictional observed values and mark which points are above or below the reference line. Label population units clearly. Logarithmic graphs cannot include a rank of zero, and a graph of only the ten largest cities says little about smaller towns. The displayed sample and the axes are part of the evidence, not decoration.
Rank-size pattern versus a primate city
A primate city is unusually dominant within the urban system being studied. Introductory geography courses often flag a largest city that is more than twice the size of the second largest, but a single two-city comparison cannot describe the whole hierarchy. Consider a fictional largest metro of 12 million and a second metro of 1.5 million. The top-to-second ratio is eight to one, much more concentrated than the simple rank-size benchmark of two to one. That result warrants investigation. It does not establish whether the cause is political centralization, port location, unequal investment, administrative boundaries, or something else.
Now imagine a second metro of 8 million beside a largest of 12 million. The top pair is closer in size than the benchmark suggests. The country might have two major economic regions, or the measured areas might overlap in ways that make their sizes hard to compare. Examine rank 3, rank 4, and the rest before declaring the system ‘balanced.’ A hierarchy can have two large centers followed by a very thin middle tier. Conversely, one large city can coexist with several vigorous mid-sized regions. The full distribution is more informative than a slogan about one dominant place.
A comparison with primacy can be useful for planning questions. It may prompt a team to ask whether people outside the largest metro can access jobs, advanced health care, universities, and transport. But population ranking is not a measure of service quality or fairness. A city-size curve cannot tell us whether housing is affordable, travel times are acceptable, or smaller places have adequate infrastructure. Those outcomes require separate evidence. For a closely related discussion of how urban form shapes access, see Sly Academy’s guide to density and land use.
What counts as a city?
The definition of the unit is the first decision in any responsible rank-size analysis. A municipality is an administrative jurisdiction. A built-up urban area is a continuous settlement identified under a statistical standard. A metropolitan or functional urban area attempts to capture a core and its connected surroundings, often using commuting. Their populations can differ dramatically. A central municipality may contain two million residents while its connected suburbs contain three million more. Ranking the municipality at two million and the functional region at five million answers different questions.
The United States Census Bureau explains that metropolitan statistical areas combine a core with adjacent counties that have strong social and economic ties, measured through commuting. Its metropolitan-area glossary is a useful official example of how a statistical boundary differs from a city government’s boundary. The example should not be applied automatically to every country: national agencies use different standards, and international comparisons need harmonized definitions. Always say whether your figures describe municipalities, built-up areas, or functional regions.
Boundary choice can change the answer even when no resident moves. Suppose an urban center expands into neighboring districts. A municipal list may show several separate places, while a functional-region list treats them as one connected labor market. If a jurisdiction redraws its legal border, the recorded city proper population may jump without equivalent demographic growth. A cross-border metropolitan region may be split in a national list. These are not minor technicalities. They can alter which place holds rank 1, the ratios among ranks, and the apparent strength of primacy.
An OECD study of city-size distributions examines how comparable functional urban areas affect the picture. Its analysis is a reminder that administrative boundaries and functional connections do not always align. It is tempting to announce that a country ‘follows Zipf’s law’ after glancing at a table of city names. A more defensible claim identifies the source, the year, the boundary definition, the minimum size threshold, and the part of the ranking being tested. Without those details, another reader cannot reproduce or challenge the conclusion.
Choosing a system and a sample
Before sorting, decide what collection of places belongs in the analysis. A national system is convenient because census tables and government boundaries are easy to obtain, but an economy’s urban connections may cross borders. Within one country, several regional networks may behave differently. A student can still use a national sample, provided the limitation is named. Define a threshold too: for example, all comparable urban areas above 100,000 residents in a stated year. A threshold makes the work manageable but means the conclusion applies only to the included range.
Small samples can create false confidence. Five cities may appear close to the benchmark by coincidence, while a wider list reveals a large gap among mid-sized areas. Including many tiny places can create a different problem if some settlements are missing or measured inconsistently. The top end and the lower tail do not have to follow the same slope. A good graph displays the observed points and states where the fit seems strongest or weakest rather than compressing everything into one adjective. The rank-size rule is a model to examine, not a verdict that replaces inspection.
Use one reference year whenever possible. Mixing a recent top-city estimate with decade-old figures for smaller cities can produce a pattern that never existed at a single time. Check whether estimates are provisional and whether agencies revised their methods. Record if the source counts students, temporary workers, or institutional residents differently across places. A precise formula does not repair inconsistent input data. If a dataset is incomplete, say so directly and avoid overstating what its line or ratio proves.
How researchers test the relationship
A basic test starts by ordering comparable population figures and assigning consecutive ranks. Compute the simple benchmark for each observation, then compare observed and ideal values in a table or graph. The log-log graph shows whether the points roughly follow a line and where they depart from it. A line drawn from the top city with a fixed slope of negative one represents the textbook benchmark. A line estimated statistically from all observations is a different object: it can have another slope and intercept. Do not present a fitted line as if it were automatically the same as the ideal rule.
Some studies estimate a power-law exponent rather than demanding exactly one over rank. This broader approach asks how rapidly size decreases as rank increases. The answer can depend on whether the investigator regresses log size on log rank or the reverse, on the sample cutoff, and on the estimator. A student need not master those technical debates to read responsibly. Check the plotted axes, the population unit, the number of cities, and whether the quoted coefficient describes the same model. A slope near negative one in one graph does not make every other test unnecessary.
Published research has challenged a universal interpretation of Zipf’s law. A cross-country study by Kwok Tong Soo examined 73 countries and found that the exact form was rejected much more often than an uncritical textbook presentation would suggest. See the study’s published research record. That finding does not make the rank-size idea useless. It means the exact relationship is a hypothesis to compare with well-defined data, not a permanent fact about every country. The OECD work on functional urban areas adds another perspective: defining cities consistently can change how closely a system appears to fit.
Be alert to selection effects. If a graph includes only the largest places, the lower end is invisible. If it includes only places inside a political border, economically connected places outside that border are absent. If a paper removes a capital because it is an outlier, its reported fit answers a narrower question than the original full sample. None of these choices is necessarily dishonest; each can be useful for a defined research aim. The key is disclosure. Ask what was included, what was excluded, and whether the conclusion is limited accordingly.
What the pattern cannot predict
A rank-size distribution is a snapshot of relative populations. It does not forecast a city’s future growth by itself. Saying that rank 4 ‘should’ contain three million residents in the 12-million example does not mean a current two-million city will gain one million residents. Growth depends on births, deaths, movement of people, housing supply, employment, land constraints, infrastructure, and public policy. A prediction requires a time-based model and evidence about those processes. Dividing a current population by a rank is not a demographic forecast.
The curve also does not establish causation. Two countries might show similar ratios for very different historical reasons. A port-based trade network, a federal political structure, and long-term industrial specialization may each influence where people live, but the population table alone does not identify the mechanism. Likewise, a steep decline after the largest city may signal concentration, yet it does not prove that a specific policy caused it. Treat the graph as a starting point for questions about economic geography, not as the final explanation.
Nor does a close fit mean that an urban system is fair, efficient, or sustainable. Residents care about water, sanitation, housing costs, schools, accessibility, safety, wages, and environmental risks. Two systems with nearly identical city-size curves can perform very differently on these measures. A policy team should connect population patterns to relevant outcomes before recommending action. For example, if smaller centers lack hospitals, the team needs travel-time and health-service data rather than only city ranks. If the concern is congestion in the largest metro, transport and land-use evidence is more direct.
A classroom method you can repeat
Step 1: define comparable areas
Choose one kind of place: municipalities, built-up areas, or functional metropolitan areas. State the agency, year, and minimum population threshold. If you compare countries, check whether the same concept is used in both. Make a short note about any known boundary changes. This setup may seem slower than immediately writing the formula, but it prevents the most serious interpretation errors. A clean definition makes a calculation explainable and reproducible.
Step 2: rank and compute
Sort the areas by descending population and assign rank 1 to the largest. Add a benchmark column using largest population divided by each rank. Add a difference or an observed-to-benchmark ratio. Check a few numbers by hand, including rank 2 and rank 4. Keep units consistent; 12 million divided by 4 is 3 million, not 3 people and not 0.003 million. If there is a tie, disclose how you assigned ranks instead of hiding a judgment inside the spreadsheet.
Step 3: graph the full picture
Plot population against rank on ordinary axes to see the shape, then make a second graph with both axes logarithmic. Draw or compute the ideal one-over-rank reference. Look for a large top-city gap, a thin middle tier, and groups of places near the reference. Note the number of points. If the graph shows only eight cities, do not generalize confidently about the entire settlement system. Keep the observed line and the ideal reference visually distinct so a reader can tell data from model.
Step 4: write a qualified conclusion
A strong conclusion might read: ‘Among the twelve functional urban areas above the stated threshold in the cited year, the second-largest area is smaller than the simple rank-size benchmark, while ranks four through eight are relatively close. The sample excludes smaller towns, so this does not describe every settlement.’ That statement names the unit, sample, finding, and limitation. A weak conclusion says that the nation obeys a universal law and therefore has ideal planning. The latter leaps from a descriptive population relation to a policy judgment without evidence.
Worked comparison: two imaginary systems
Imagine systems A and B, each with a largest functional urban area of 10 million residents. In A, ranks 2 through 5 contain 5.2 million, 3.1 million, 2.6 million, and 1.9 million people. The simple benchmarks are 5 million, about 3.33 million, 2.5 million, and 2 million. A is reasonably close across these ranks, though formal research would need a defined measure of fit. In B, ranks 2 through 5 contain 1.8 million, 1.5 million, 1.1 million, and 0.9 million. Its largest area dominates far more strongly than the simple benchmark suggests. Neither pattern tells us by itself why these systems differ.
Now suppose B’s second through fifth entries are municipalities inside the same commuting region as its first entry. Treating those fragments as independent cities changes the apparent hierarchy; a functional-area analysis may combine them. Or suppose A’s second urban region crosses an international border and a national table counts only one side. Its rank could change under a wider definition. These examples show why even a correct calculation can support a poor conclusion if the underlying units are inconsistent. Define the places before debating which system is more ‘balanced.’
Common misconceptions
‘The second city must be exactly half the first.’ No. One half is the ideal benchmark at rank 2, not a legal or physical requirement. A real second city may be larger or smaller. Say whether the observed value is close to the benchmark and whether the difference is meaningful for the question you are asking. Avoid treating a rounded estimate as exact. The same caution applies at every rank.
‘The normal rank-population graph is a straight line.’ No. The one-over-rank formula curves on linear axes. Its exact points align when both rank and population are plotted logarithmically in the usual orientation. A student who labels only ‘rank’ and ‘population’ without specifying the scale can easily misread the result. Graph design is part of the explanation, not merely presentation.
‘Zipf’s law predicts next year’s population.’ No. A cross-sectional relation among present city sizes is not a growth forecast. Population changes through demographic and economic processes, and a city can change rank without reaching a theoretical target. If an assignment asks about future growth, distinguish a descriptive benchmark from a prediction and identify the extra evidence a forecast would require.
‘A close fit proves good planning.’ No. The curve does not measure well-being or access. A smooth hierarchy may coexist with costly housing and weak services; a concentrated hierarchy may coexist with strong public services outside the dominant city. The appropriate planning question is not simply whether a slope equals negative one, but what residents in different places can actually reach and afford. Sly Academy’s urban-change challenges guide introduces several related pressures that require their own evidence.
‘All sources mean the same thing by city.’ No. City proper, built-up area, and metropolitan area are distinct. When copying figures into a table, write the unit beside every source. If a dataset mixes them, repair or qualify it before drawing a conclusion. A visible citation is not enough if the cited figure uses a different boundary from the other figures in the same analysis.
Using the idea in geography writing
For an exam answer, first define rank and the area type, then state the approximation, calculate one correct benchmark, and interpret an observed departure. If a prompt mentions a primate city, compare the largest and next-largest places, but note that the rest of the hierarchy can strengthen or weaken the initial impression. If a graph uses log scales, explain why the simple inverse relation becomes a straight line there. Avoid naming countries as permanent examples without a current, consistent dataset. Populations, boundaries, and statistical methods change.
For a longer project, add one further layer: connect the population pattern to a specific, testable question. Perhaps you want to know whether mid-sized regions have access to jobs, whether a dominant metro attracts most new housing, or whether transport links affect regional opportunity. Then gather outcome measures that match that question. The rank-size table can help select cases for closer study, but it cannot replace observation on the ground. Related Sly Academy reading on high population density clarifies another often-confused concept: density concerns people per unit area, while rank-size concerns total populations ordered across places.
Key takeaway
The rank-size rule is most useful as a clear comparison, not as an unquestioned law. Use a defined set of comparable areas, one reference year, and a stated population source. Calculate the simple benchmark accurately, graph it on the right axes, and inspect departures across the entire sample. Explain what the evidence shows and what it cannot show. A careful answer leaves room for boundaries, history, economics, and policy without pretending that one elegant formula can predict or judge the future of every city.